Agentic AI Guardrails Implementation Patterns
Controls must sit in the agent's execution path, not just in prompts or filters.
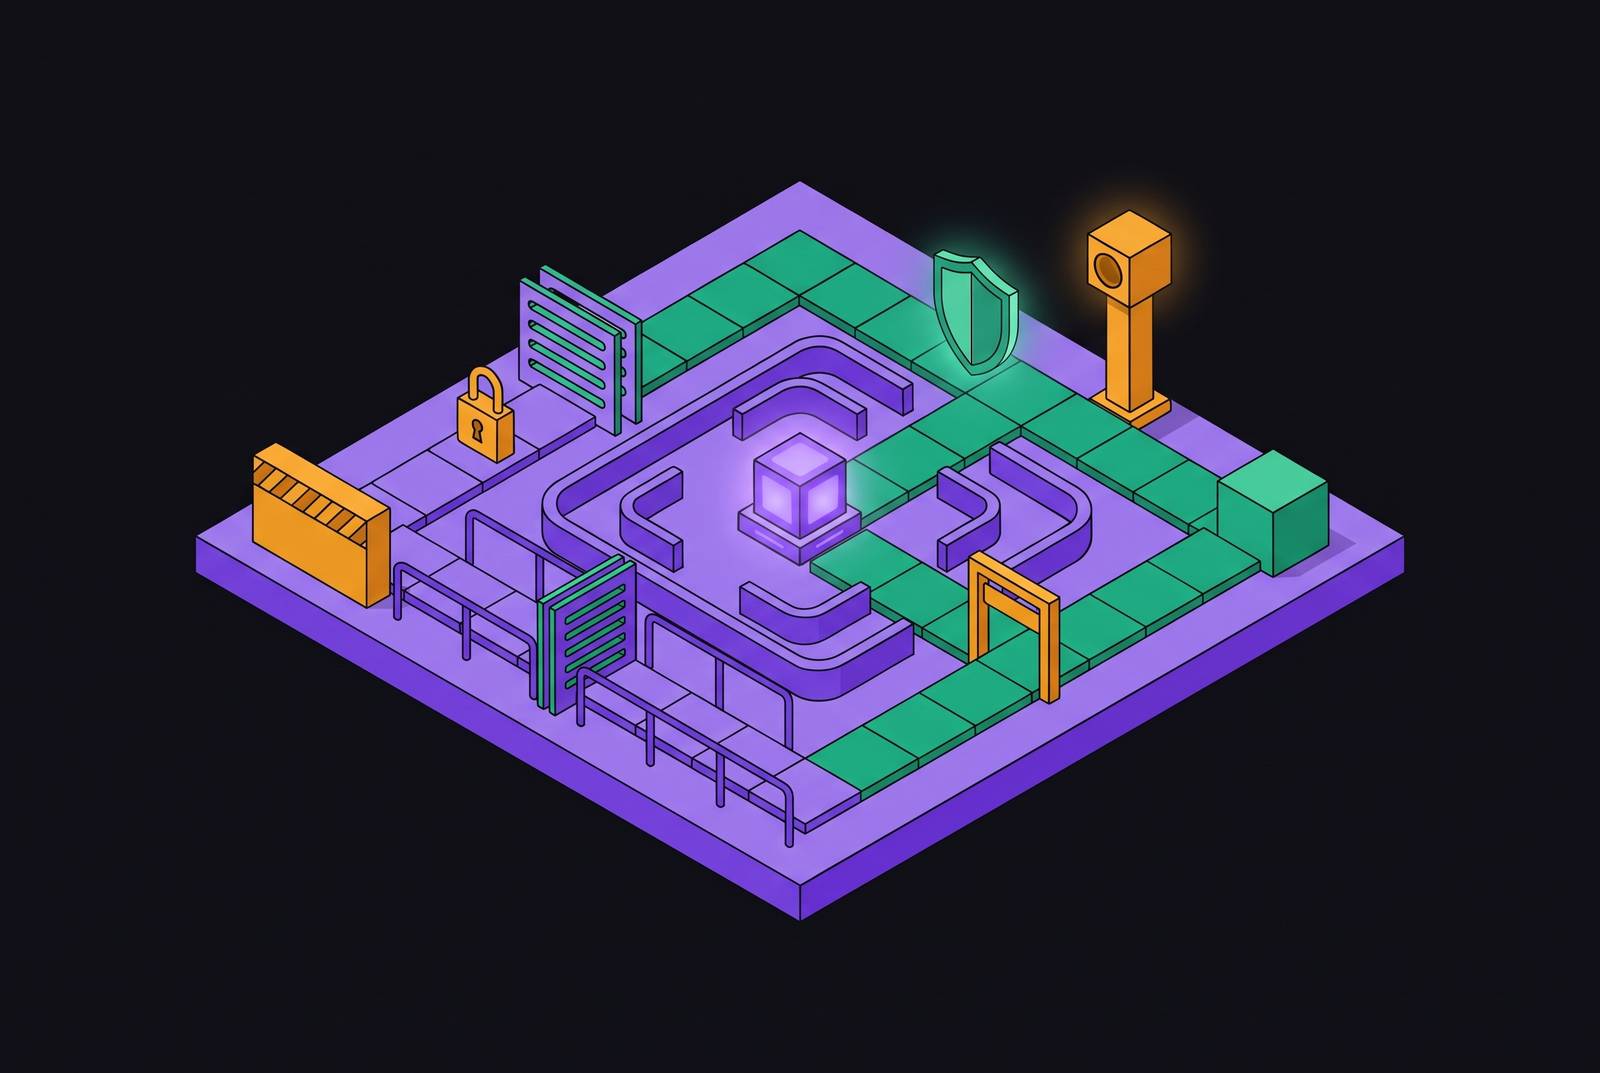
Agentic AI guardrails are an execution architecture. Effective implementation puts identity, permissions, context controls, approval gates, and live visibility directly in the agent’s path. The goal is plain enough. An organization must control what an agent can do before it acts, and be able to prove that control afterward.
Why prompt filters fail when agents act instead of answer
A request to “prepare a quarterly report” can send an agent into a CRM, then into financial databases, then out to fetch external data. It generates visualizations and emails the result. Each step is another autonomous decision with its own compliance implications. The final report is only the visible end of that chain.
That changes where a mistake becomes dangerous. A chatbot can give a bad answer that a person rejects. An agent can modify a database, trigger a payment, or route a decision before anyone sees its output. The correction window closes when the tool call fires.
An agent with over-provisioned access through a Model Context Protocol server can retrieve personal information before a content filter sees the response. System prompt instructions and classifiers do not replace access restrictions at that boundary. Production governance therefore needs controls over data access, tool use, execution boundaries, and approval requirements.
The layered architecture that production guardrails require
IBM Research’s CUGA system puts checkpoints along the execution path, including at the end. Shlomov et al. describe the system in ACM CAIS’26. Its Intent Guard intercepts out-of-scope intent before planning, while Playbook steers reasoning through structured tool sequences. Tool Guide checks usage before invocation. Tool Approvals places human review outside the reasoning loop, and Output Formatter controls the final response.
The placement is the point of the pattern. A rule about intent belongs before planning, while a rule about a production change belongs before the tool executes. The policy layer works with the model without fine-tuning it.
Across the wider architecture, those checkpoints protect distinct surfaces, including data access, context delivery, tool invocation, and end-to-end auditability. Inventory and lifecycle controls establish what is running, while runtime enforcement constrains its behavior. Observability then shows whether those constraints hold. A policy document can describe this design, but only controls in the execution path can enforce it.
Agent identity as the foundation every other control depends on
Every checkpoint needs to know which agent it governs. An anonymous process, or an agent using a developer’s administrator credentials, breaks that link. Permissions no longer describe the agent’s intended authority, and logs cannot reliably attribute its actions. Revocation becomes harder for the same reason.
The implementation starts with an agent registry. Each entry should tie a stable, unique identity to a purpose, an owner, authorized tools, and a defined data access scope. Access rules and approval requirements can then attach to that identity. The registry becomes the authoritative account of which agents exist and what they may do.
Microsoft Entra Agent ID became generally available in April 2026. Google Cloud’s Gemini Enterprise Agent Platform also introduced Agent Identity, giving agents unique cryptographic IDs. These frameworks give agents identities, but a registry alone does not reveal agents built outside the approved path. Discovery through telemetry, MCP server monitoring, network analysis, and platform APIs closes that gap.
Why standard RBAC is not sufficient for agents, and what replaces it
Role-based access control, or RBAC, falls short when it must account for how prior actions combine. A compliance reporting agent and a data quality agent can each stay within their permissions while their combined outputs cross an information barrier. That can create a GDPR risk even when neither permission looks wrong on its own. The sequence changes the risk of the action.
RBAC therefore needs attribute-based access control, or ABAC, evaluated at query time, with enforcement that accounts for prior actions. Source-system permissions should propagate through retrieval to context delivery. A warehouse rule loses its force if the MCP server hands the same data to an agent under a separately configured, broader permission set.
In practice, row-level and column-level access should be checked when a query runs, with personal-information classifications enforced dynamically. Static dataset labels are not enough for this. Each agent should get only the tools and data sources it has been expressly allowed to use, with no catch-all grants or inherited administrator access.
Context governance: the enforcement layer teams consistently overlook
Permission to retrieve data does not establish that the retrieved payload is suitable for the model. An authorized document may still be stale, corrupted, untagged, or unvalidated. Access control answers who may read it. Context governance answers what actually reaches the model and whether that input can later be reconstructed.
Each delivered context bundle should be a versioned artifact tied to a specific retrieval event. Personal-information classifications, sensitivity labels, and data sources should be attached before delivery. The exact payload should also be sanitized and inspected before model submission, rather than judged indirectly from the resulting answer.
Persistent memory extends this problem beyond a single request. Vector stores, logs, and knowledge graphs can preserve mistakes or let context bleed across tenants and time periods. Output filtering cannot repair that structural separation. EU AI Act Article 10 covers data governance and dataset quality, so this work matters for more than keeping data engineering in good order. Context versioning helps control how context is delivered, while the Act’s rules on logging fall separately under Article 12.
Human-in-the-loop triggers: deciding which actions require approval before execution
High-impact actions need a gate before the tool executes. Payments, outbound customer communications, production database or configuration changes, and decisions affecting individual rights cannot depend on the model deciding to ask permission. CUGA’s Tool Approvals checkpoint sits outside the reasoning loop for that reason. The agent does not get to waive the gate.
These actions should be classified at design time, with the triggers encoded in the policy layer. Identity establishes who is acting, permissions establish its authority, and governed context makes the proposed action reviewable. Human approval then becomes an explicit execution condition. Review after a production change is a postmortem.
Colorado’s automated decision-making law, SB 26-189, takes effect January 1, 2027, making review and documentation design a concrete deployment concern. EU AI Act Article 14 also requires people to oversee high-risk deployments. Clear paths for approval help meet those rules without making people do every step by hand. The avoidable friction comes from undefined workflows that leave teams negotiating authority during execution or responding after damage occurs.
Gateway enforcement: centralizing policy so it cannot be inconsistently applied
Approval rules become unreliable when each team implements them differently. The same problem affects access checks and filtering when different engineering groups build the agents. A centralized AI gateway gives teams one place to enforce the rules. Moving policy out of bespoke application code makes coverage assessable across the estate.
At that boundary, ingress filtering checks prompts and retrieved context for injection attempts, out-of-scope requests, and unauthorized payloads. Egress filtering inspects generated outputs for credential leaks, hallucination, and unauthorized API execution requests. These are named controls with audit trails. Routing microservices to a centralized base URL also avoids rewriting core application logic for the gateway transition.
The same pattern applies to MCP infrastructure. Access tokens pass through the gateway, tool invocations are logged at its boundary, and policy changes propagate from one place. Each server also needs a registry entry because an unaccounted server is an unmonitored access path. A governed route gives teams a way to use tools without shadow adoption, while a ban alone can push that use out of sight.
What real-time observability means and why post-incident logs do not substitute for it
“If one of these agents executes a flawed transaction tomorrow, can you prove you had operational control the entire time?” That question requires more than a record of the final answer. A post-incident log can explain what happened. Real-time observability shows what is happening while there is still time to step in.
The execution trace must include retrieval steps, tool calls, the full agent chain, and user-facing output. OpenInference semantic conventions capture richer LLM, retrieval, and tool detail than the OpenTelemetry GenAI specification alone. That detail exposes where compliance-relevant actions occur. Telemetry should also map to applicable frameworks, including SOC 2, GDPR, HIPAA, and relevant EU AI Act articles, so stored evidence is usable.
Cross-agent workflows make this visibility especially important. Individually permitted steps can combine data in ways that breach an information barrier, which isolated agent logs may fail to reveal in time. End-to-end lineage shows how those steps combine data across the chain. Observability is therefore the feedback mechanism for the architecture, allowing evidence from execution to improve permissions, context controls, and approval policies.
Applying the architecture to U.S. state privacy law obligations that agents now trigger
U.S. state privacy laws make these engineering controls part of how organizations meet their legal duties. The requirements differ, so one generic claim of “AI compliance” is not enough. CCPA/CPRA regulations made risk assessments and cybersecurity audits effective January 1, 2026, while automated decision-making rules apply January 1, 2027.
Connecticut SB 1295, effective July 1, 2026, requires a clear statement of whether consumer personal data is used to train large language models. Its scope is limited to LLM training. The Connecticut Artificial Intelligence Responsibility and Transparency Act, signed May 27, 2026 as Public Act 26-15, adds AI-specific obligations. Colorado’s law adds another reason to design human-review and automated decision-making documentation into deployment.
RBAC and ABAC support data minimization and purpose limitation, while versioned context provides lineage for risk assessments. Approval gates help with the review of automated decision-making, and gateway logs give teams evidence with timestamps that they can query. None of these mechanisms establishes compliance by itself, but each makes an obligation enforceable and demonstrable.
How the EU AI Act, GDPR cumulative exposure, and global frameworks change the production calculus
The EU AI Act’s December 2027 deadline for high-risk AI systems makes governance a production requirement for affected deployments. Article 10 addresses data governance and dataset quality, Article 12 requires automatic event logging, and Article 14 requires human oversight. These duties reach different parts of execution. A static policy cannot substitute for their implementation.
GDPR exposure also reaches beyond model training. An agent that retrieves personal data to construct a response is processing that data and needs a lawful basis, documented governance, and transparency. Cumulative GDPR fines since 2018 have reached €7.1 billion.
Brazil’s LGPD, China’s PIPL, South Africa’s POPIA, India’s DPDPA, and Saudi Arabia’s PDPL broaden the regulatory picture for multinational enterprises. Their shared concerns include lawful processing, minimization, transparency, oversight, and retained evidence, though the applicable duties differ. Jurisdiction-specific requirements still need policy treatment, but the underlying enforcement infrastructure need not be rebuilt for each regime.
Governance as the condition for moving fast, not the reason for moving slowly
A defined control path gives organizations a basis for approving production deployment. Without it, uncertainty about access, responsibility, and recovery becomes a reason to stop. Skipping an approval gate shifts that work into incident response, where the choices are worse and the disruption is greater.
Centralized enforcement also changes the cost of growth. A shared gateway propagates policy changes from one place, while hardcoded per-agent rules require changes across individual deployments.
The next stage of adoption depends on making access visibility a basic operational right. Teams need a dependable way to establish what agents may do and see when they depart from it. Giving teams that ability before they expand lets agents do more work on their own. Waiting until after deployment makes every new workflow another unresolved question about whether it belongs in production.